Host it yourself — verified in our lab

Computers capable of running Llama 3.3 70B Instruct

What PC do you need to run Llama 3.3 70B Instruct? 42 GB VRAM at Q4 (141 GB FP16) — see the exact AI workstations that host Llama 3.3 70B Instruct locally, from $1,799.

Q4 (RECOMMENDED)
42 GB
Q8
75 GB
FP16
141 GB

AI workstations that I can host Llama 3.3 70B Instruct
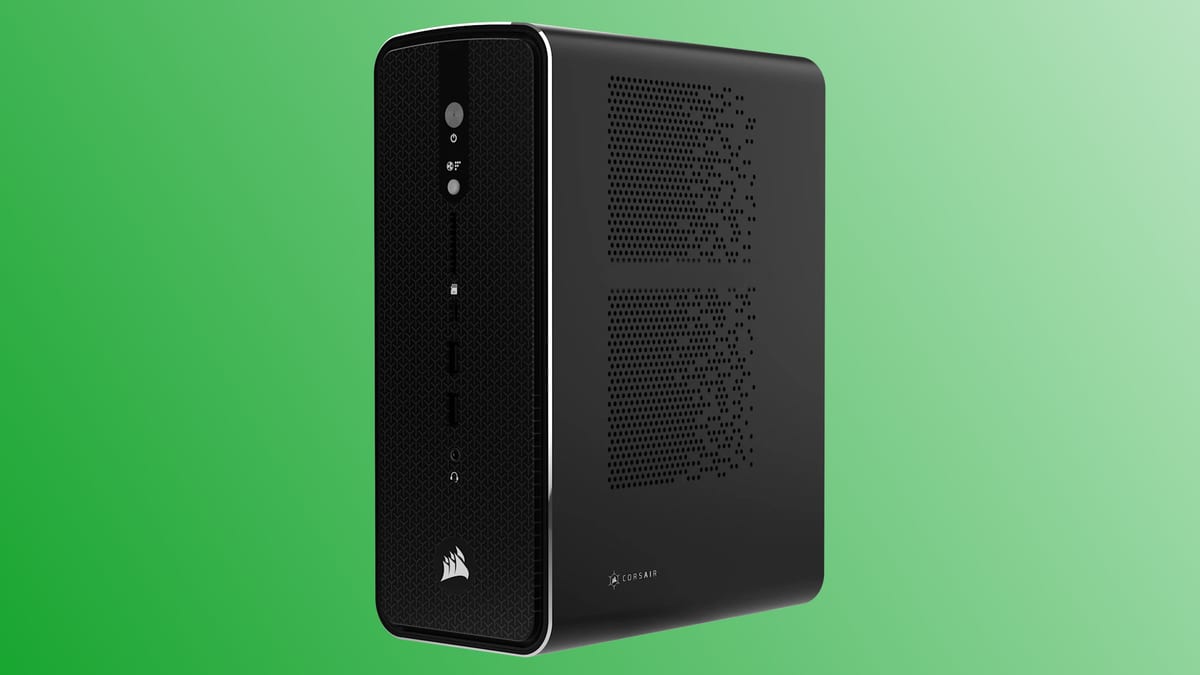
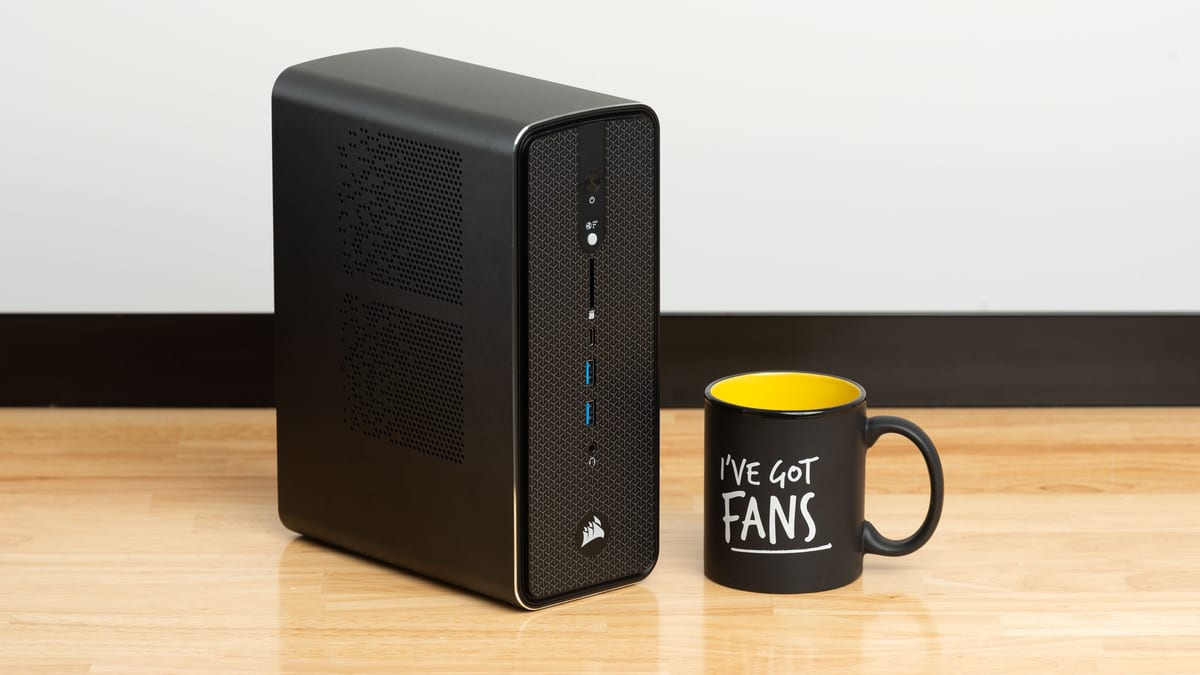
Corsair AI Workstation 100
Best value to run this
Corsair AI Workstation 100
48 GB VRAM · 1× GPU · Corsair
$1,799
Buy
Corsair AI Workstation 200
48 GB VRAM · 1× GPU · Corsair
$1,999
Buy
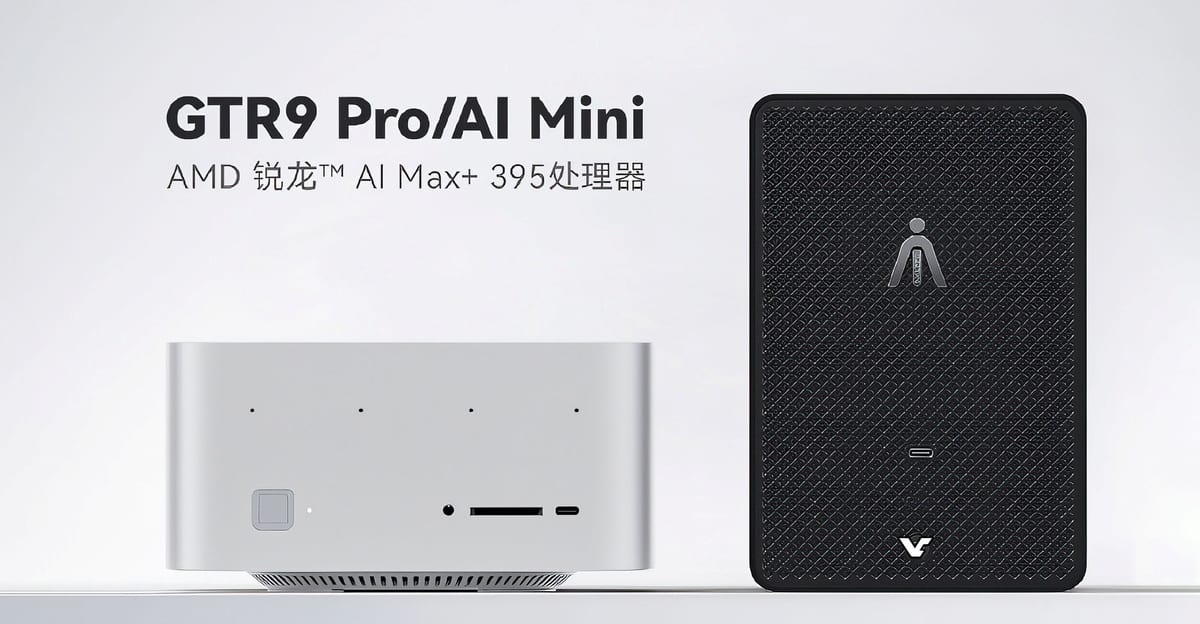
Beelink GTR9 Pro
Beelink GTR9 Pro
96 GB VRAM · 1× GPU · Beelink
$1,999
Buy
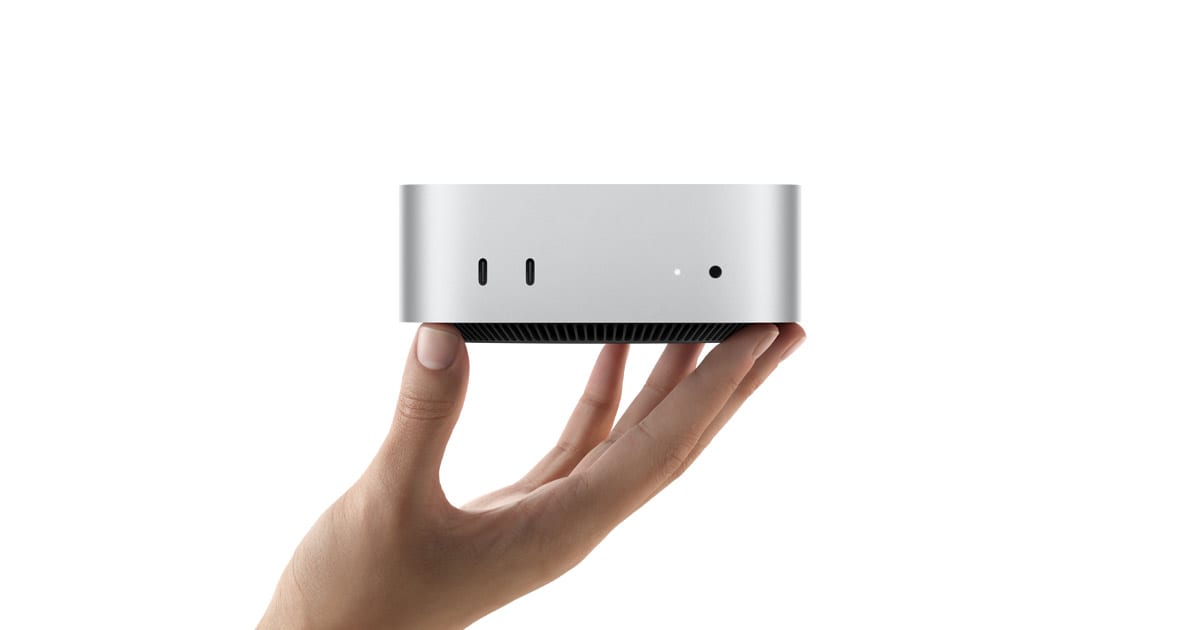
Mac mini (M4 Pro, 64 GB)
64 GB VRAM · 1× GPU · Apple
$2,199
Buy
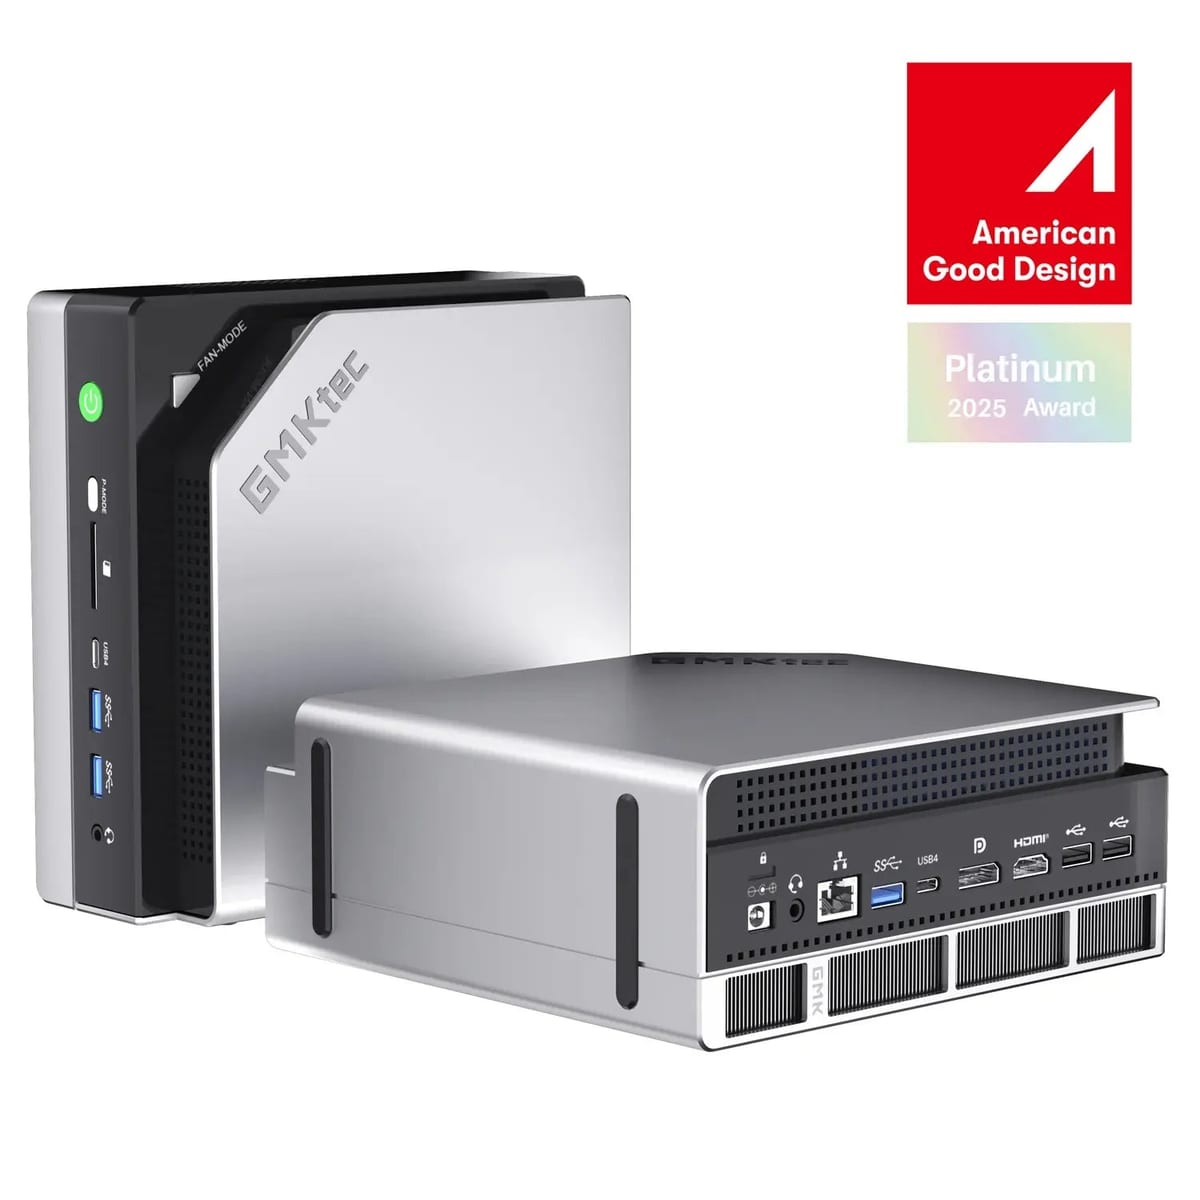
GMKtec EVO-X2
GMKtec EVO-X2
96 GB VRAM · 1× GPU · GMKtec
$2,199
Buy
Corsair AI Workstation 300
96 GB VRAM · 1× GPU · Corsair
$2,299
Buy
Browse all machines → Analyze another model Different specs? Get a quote

Frequently asked

What PC do I need to run "Llama 3.3 70B Instruct"?

At Q4 quantization Llama 3.3 70B Instruct needs about 42 GB of VRAM — the cheapest match in our catalog is the Corsair AI Workstation 100 (48 GB, $1,799). At Q8 plan for 75 GB, at FP16 141 GB.

How much VRAM does "Llama 3.3 70B Instruct" need?

Llama 3.3 70B Instruct requires roughly 42 GB at Q4 (recommended for local use), 75 GB at Q8 and 141 GB at FP16, including KV-cache headroom.

Can I run "Llama 3.3 70B Instruct" locally on my own computer?

Yes — with the right hardware. Any workstation with at least 42 GB VRAM runs Llama 3.3 70B Instruct locally, such as the Corsair AI Workstation 100. No cloud, no per-token bills.

Which GPU runs "Llama 3.3 70B Instruct"?

The Radeon 8050S in the Corsair AI Workstation 100 (48 GB total) is the entry point; larger multi-GPU builds scale to 75–141 GB for Q8/FP16.

Cheap computer for Llama 3.3 70B Instruct

The most affordable way to host Llama 3.3 70B Instruct: a 42 GB-VRAM workstation — from $1,799 (Corsair AI Workstation 100), which typically pays for itself vs. $1–4/hr cloud GPUs.

Llama 3.3 70B Instruct fine-tuning machine

Fine-tuning Llama 3.3 70B Instruct needs the FP16 size — about 141 GB of VRAM (fits: Mac Studio (M3 Ultra, 512 GB), Bizon G3000 G2 — 2× RTX PRO 6000).

People also search for

AI workstations that I can host "Llama 3.3 70B Instruct"Computers capable of running "Llama 3.3 70B Instruct"Computers where I can use "Llama 3.3 70B Instruct"What PC do I need to run "Llama 3.3 70B Instruct"?Best workstation for "Llama 3.3 70B Instruct"How much VRAM does "Llama 3.3 70B Instruct" need?Can I run "Llama 3.3 70B Instruct" locally on my own computer?Llama 3.3 70B Instruct local machine requirementsWorkstation build for Llama 3.3 70B InstructMinimum hardware for Llama 3.3 70B InstructRun Llama 3.3 70B Instruct without the cloud — on your own hardwareDesktop PC for Llama 3.3 70B Instruct inferenceWhich GPU runs Llama 3.3 70B Instruct?Llama 3.3 70B Instruct ready workstations for saleBuy a PC to run Llama 3.3 70B InstructRun Llama 3.3 70B Instruct on-premisesLlama 3.3 70B Instruct home server buildCheap computer for Llama 3.3 70B InstructHigh-end rig for Llama 3.3 70B InstructLlama 3.3 70B Instruct fine-tuning machineHost Llama 3.3 70B Instruct yourself — alternative to cloud APIsLlama 3.3 70B Instruct GPU memory requirements